Showing posts with label Machine Learning. Show all posts

27 September 2016

A Beginner's Guide to Apache Flink – 12 Key Terms, Explained


Overview
In this post, I will go through 12 core Apache Flink concepts to better understand what it does and how it works. This article could perfectly serve as a beginner's overview of Flink and Streaming engine terminology.


1.      What is Apache Flink?

At first glance, the origins of Apache Flink can be traced back to June 2008 as a researching project of the Database Systems and Information Management (DIMA) Group at the Technische Universität (TU) Berlin in Germany.

Apache Flink is an open source platform for distributed stream and batch data processing, initially it was designed as an alternative to MapReduce and the Hadoop Distributed File System (HFDS) in Hadoop origins.

According to the Apache Flink project, it is an open source platform for distributed stream and batch data processing. Flink’s core is a streaming dataflow engine that provides data distribution, communication, and fault tolerance for distributed computations over data streams. Flink also builds batch processing on top of the streaming engine, overlaying native iteration support, managed memory, and program optimization.”

17 December 2015

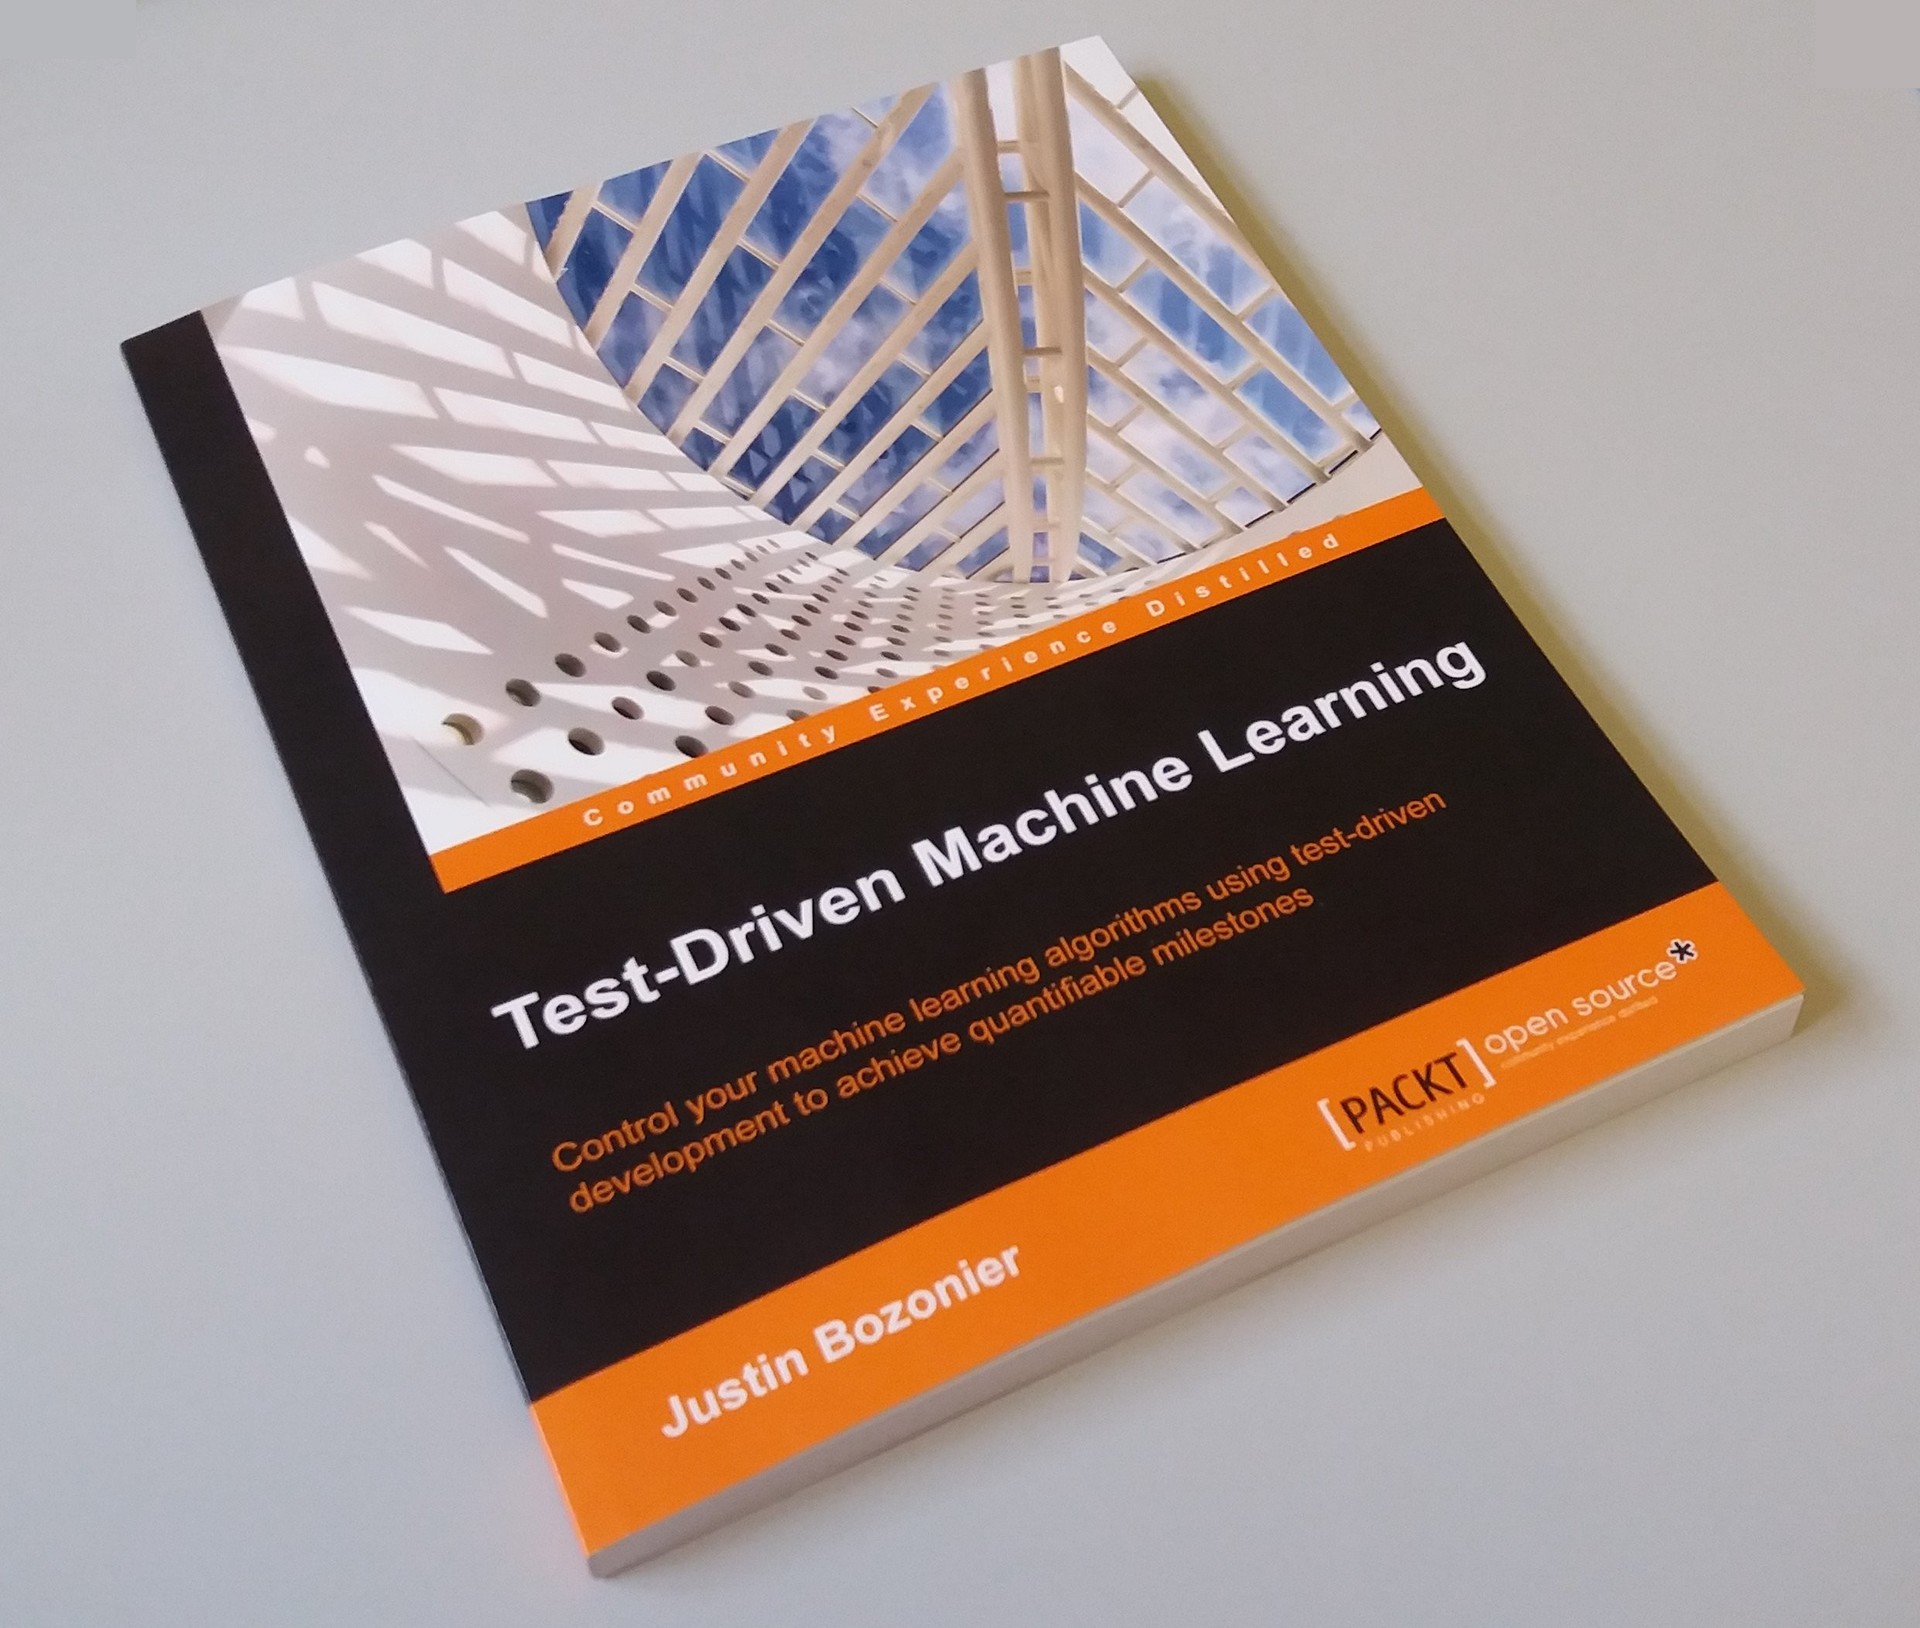
Test-Driven Machine Learning

Test-Driven Machine Learning

The book “Test-Driven Machine Learning” by Justin Bozonier, published by Packt Publishing, is in print now. I was a technical reviewer of this book, and in this post you will learn some details about it. The book is available on the publisher’s website as well as on Safari Books Library.

19 October 2015

Data Science Interview Questions

Data Science Interview Questions


Source: Data Science: An Introduction

Our IT4BI Master studies finished, and the next logical step after graduation is finding a job. I was interested in Data Science jobs and this post is a summary of my interview experience and preparation.

The term “Data Science” is not yet well establish, so interviews for Data Science jobs might include a very broad range of questions, depending on the interpretation of the term by a particular company. In this post I attempt to organize Data Science interview questions in some usable form, but it might also be biased by how I see Data Science myself. I hope you also can find it useful.

9 March 2015

Naive Bayes on Apache Flink

In this blog post we are going to implement a Naive Bayes classifier in Apache Flink. We are going to use it for text classification by applying it to the 20 Newsgroup dataset. To understand what is going on, you should be familiar with Java and know what MapReduce is. If you have seen and understood a word count example in any system, you're good to go. If you haven't heard of MapReduce or haven't seen the word count, you may first have a look at our introductory post "Hadoop and MapReduce".